Why sixteen zeros are the most honest figure in the radar
Florian Berger · Sep 15, 2026
The ai-discovery-radar measures each month how many websites in a fixed sample of 30,000 domains actually serve machine-readable discovery and consent files — and from today it is open how those numbers come about. The Technical Report v1.0 (DOI 10.5281/zenodo.22769680, CC BY 4.0) documents classification, denominator rule, sampling and verification so that every published share can be traced and challenged.
This is not a results paper. It is the instruction for reading results correctly — including our own.
What "adoption" means here — and what it does not
In the radar, adoption means: a route is publicly retrievable and the response is syntactically valid. Nothing more. Whether any crawler reads the file, whether it is current, whether it achieves anything — the radar does not measure that, and the report says so in its first section.
Three readings it rules out explicitly:
- "x % of websites support AI discovery" — the frame is not the web, and 34 named routes are not "AI discovery" in general.
- "format X is used by x %" — availability is not use.
- "adoption grew" — two measurement points under two ruleset versions are not a trend.
The safe form of every figure is: x % of the hosts observed for this route in this month's run, on frame 2026-Q3.
The denominator is the most important decision
A host that turns the measurement away with a bot wall may well have the file. A host whose robots.txt forbids us the path may have it. Counting both as "not present" pushes every share down — and unevenly, because walls concentrate in the popular ranks.
That is why the radar knows seven states plus "not measured", and only four of them form the denominator: present, alias, soft-404, absent. Blocked, forbidden, unreachable and not measured stay out. This rule arrived with ruleset 0.3.0 and affected roughly one fifth of every denominator; the August figures were republished as a result. It is in the version history — errors in the instrument are documented, not quietly corrected.
The sixteen zeros
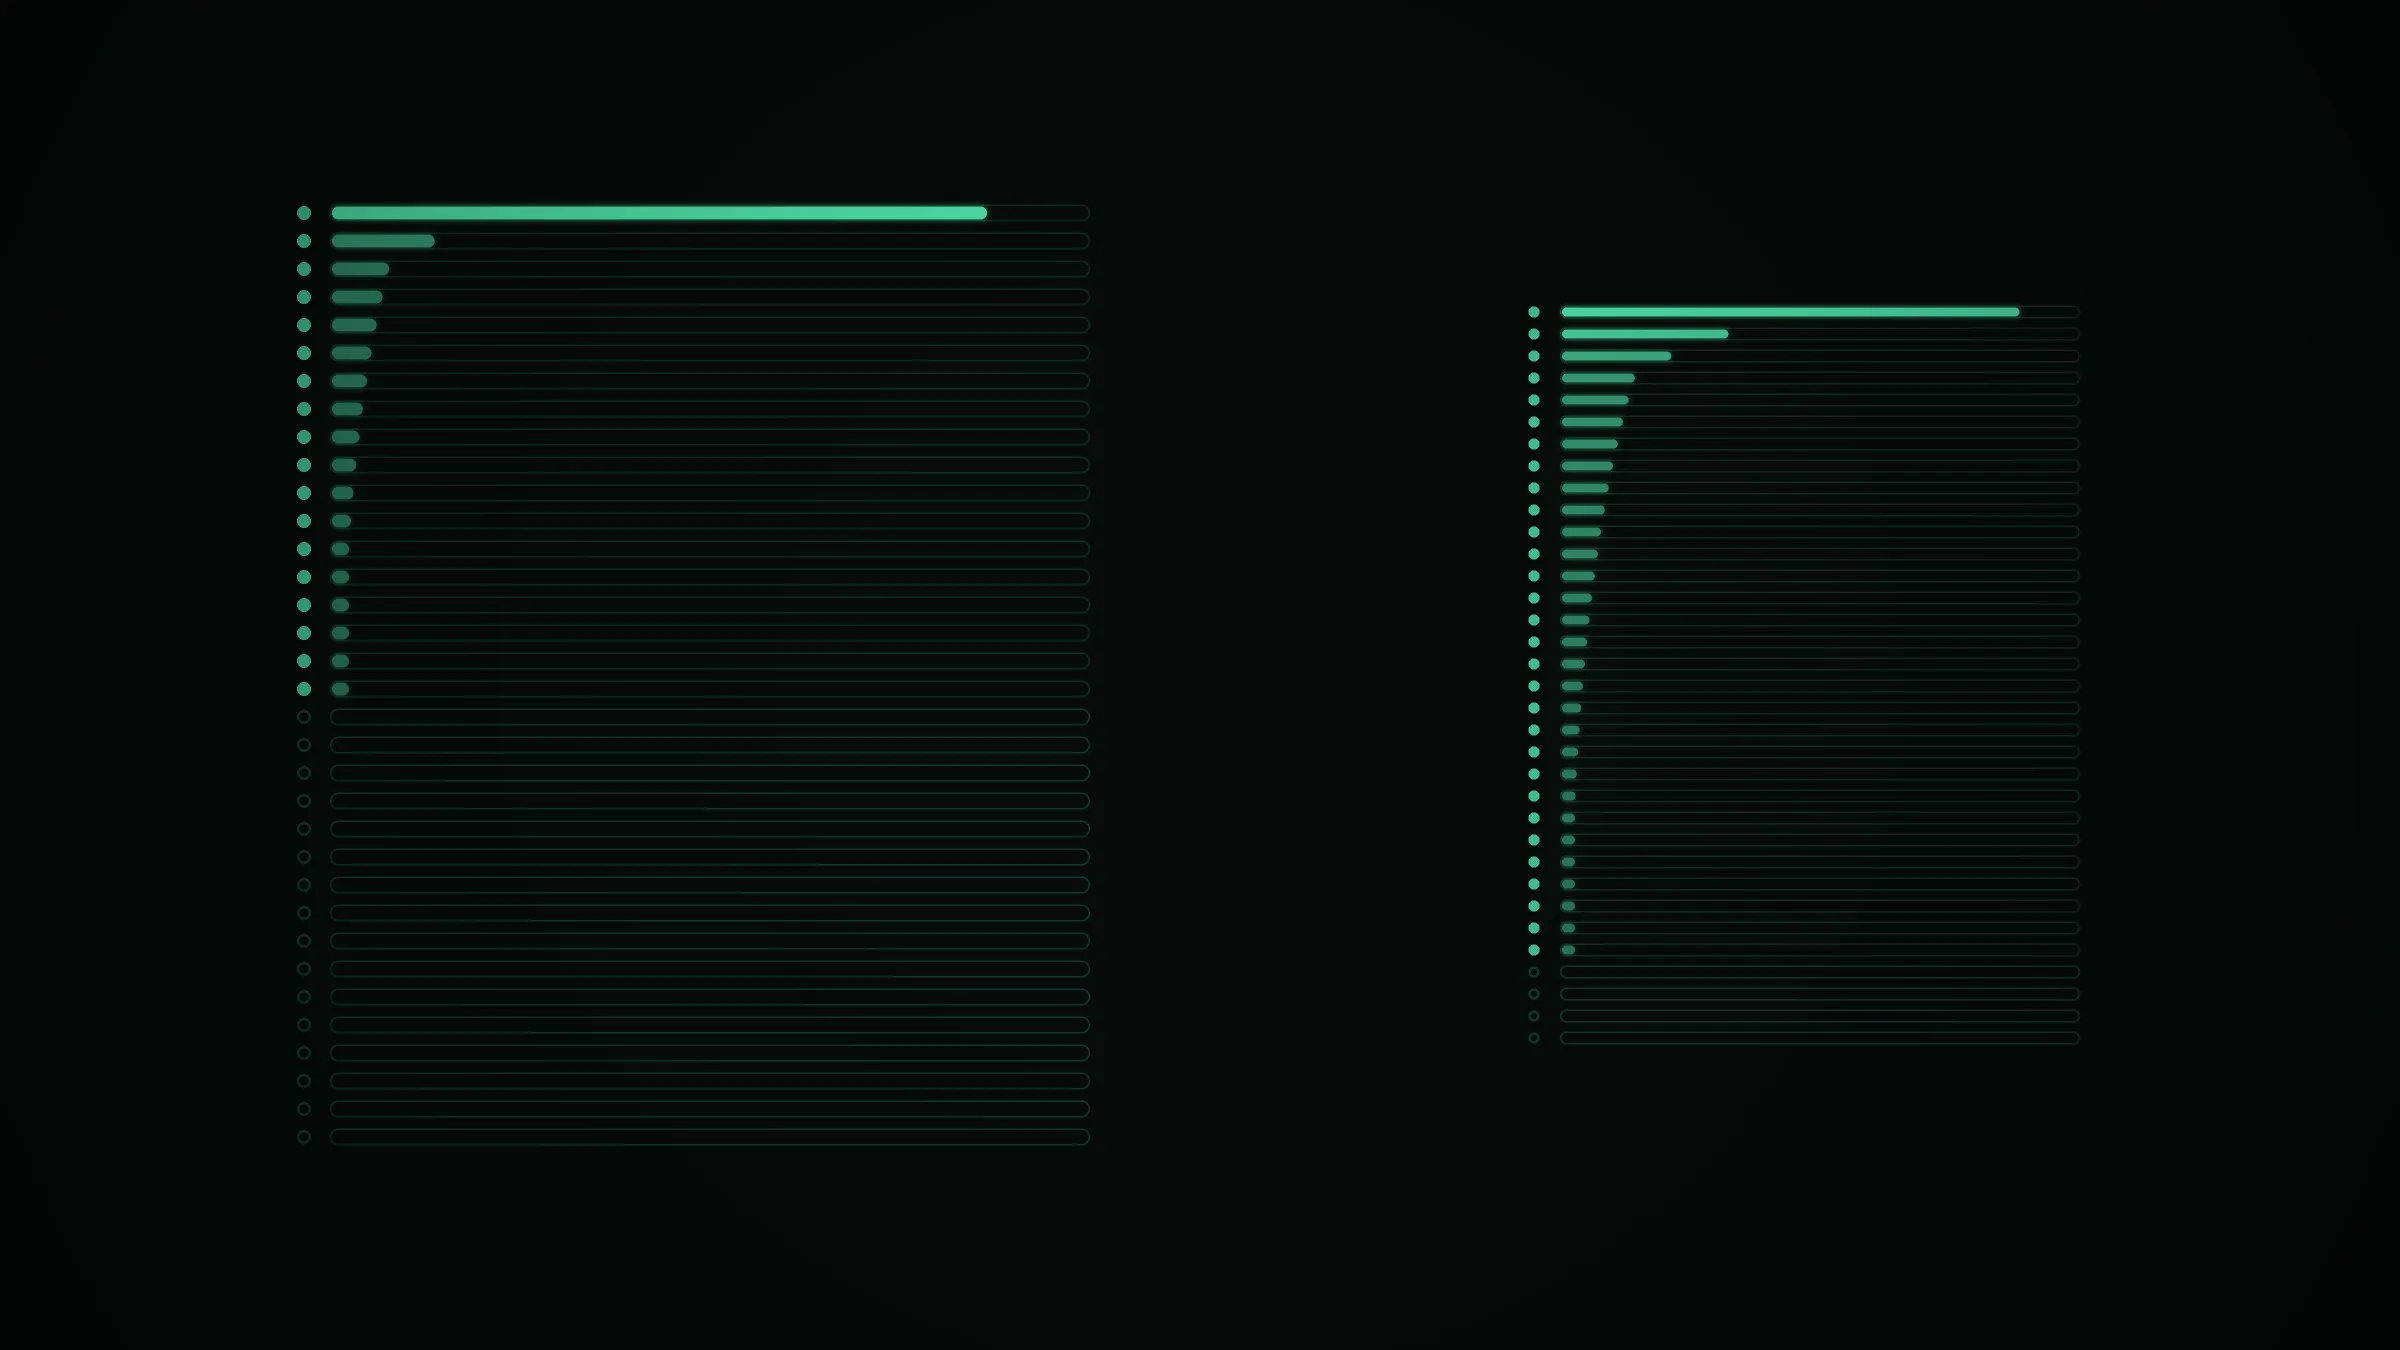
September 2026, panel of 1,000 domains (853 reachable): robots.txt 86.2 %, llms.txt 13.5 %, and 16 of 34 catalogued routes without a single hit.
The zeros are the result, not a measurement failure — many of these formats are discussed as though they were established. But the size of the zero depends on the sample: in the ten-times-larger block of the same month (around 9,700 domains, 9,206 of them reachable), only 4 of 34 routes stay at zero. A zero on rare routes across 1,000 domains is a sample-size floor. Anyone citing it as "absence" is citing it wrongly.
Consequence, decided on 15 September: from the October run the panel grows to 10,000 domains, drawn with the same generator from the same frozen frame; the 1,000-domain series continues as a subset, so that August and September remain comparable.
Four measurement traps that cost us data
- The HTTP status lies. Large platforms answer 200 on every path. One microblogging service returns
{"ok":-100}for everything — valid JSON, no file. Only what carries the specification's required key counts as valid:{"gpc":true}is an adoption,{"ok":-100}a fallback. - Bot walls answer with 404. Without checking the response body they are indistinguishable from a genuine 404 — and would count as "not adopted".
- The Range header is a trap. 454 responses of 206, 311 ignored it, about ten aborted in one pilot run. A streaming cap does the same job without the side effects.
- Templates look like adoption. One shop platform places identical text in robots.txt, llms.txt, llms-full.txt and an agents file on every shop — five hosts, one template, zero findings. The same value on every host carrying it is a signature, not a finding.
What the report deliberately leaves open
The largest unknown has a section of its own: the hosts behind walls. Both directions are plausible — whoever invests in a bot wall may be more likely to publish a policy for machines (in which case the open web understates adoption); or the wall is the policy (in which case it overstates it). The pilot cannot tell them apart. The report names what would be needed: a calibrated wall share per stratum, a wider panel, and a legitimate second channel — declared cooperation with operators, never circumvention.
And it says what nobody has checked yet: the re-derivation before every release is an internal control, not an external audit. The raw archives stay private, because they hold response bodies and therefore personal data. What is published are the protocol, the checksums and the procedure — enough to examine the method and request a re-evaluation, not enough to run the classifier yourself. That, too, is stated in the report.
Why we do this
We build websites meant to be found by people and by AI systems. btlabs Core serves several of the measured routes by default — which is exactly why the conflict of interest appears in the report as a table, concern against safeguard. Ruleset frozen and versioned, every route published including those at zero; no single domain in the result.
Numbers instead of assumptions. Anyone doubting one of them finds the procedure openly documented — and can request a re-evaluation.
Links: Technical Report v1.0 — doi.org/10.5281/zenodo.22769680 · Dataset (concept DOI) — doi.org/10.5281/zenodo.22178282 · Radar page with citation card: /en/ai-discovery-radar · Repository: github.com/flober81/ai-discovery-radar
Frequently asked questions.
What does the ai-discovery-radar measure?
The ai-discovery-radar measures each month how many websites in a frozen sample of 30,000 domains actually serve 34 catalogued machine-readable discovery and consent files — robots.txt, llms.txt, TDMRep or agent cards, for example. What is counted is availability, not use.
Why do bot walls not count as "not present"?
A host that refuses the measurement may well have the file. Blocked, forbidden and unreachable hosts are therefore kept out of every denominator; the adoption rate applies to observable hosts only.
Does 0 % in the panel mean nobody uses the format?
No. For rare routes, a zero across 1,000 domains is a sample-size floor: in the ten times larger block of the same month only 4 routes sit at zero instead of 16. From the October 2026 run the panel is therefore widened to 10,000 domains.
Where is the method documented?
In the Technical Report v1.0 on Zenodo (DOI 10.5281/zenodo.22769680, CC BY 4.0): classification model, denominator rule, sample design, verification procedure and measurement pitfalls.
Can my domain be excluded?
Yes, with no questions asked and no reason required: an e-mail naming the domain, an issue in the repository, or a Disallow line for the token ai-discovery-radar in robots.txt. Excluded domains are skipped before any request is made.